I simulate workplaces and economies to study how agents work, trade and organise themselves. This is experimental economics for the agentic economy: testing the rules and institutions we will need.
I’ve wanted to build little worlds since I was a kid. Companies, towns, societies. Now I can! And put AI agents inside them, give them things to do, and see how those worlds change.
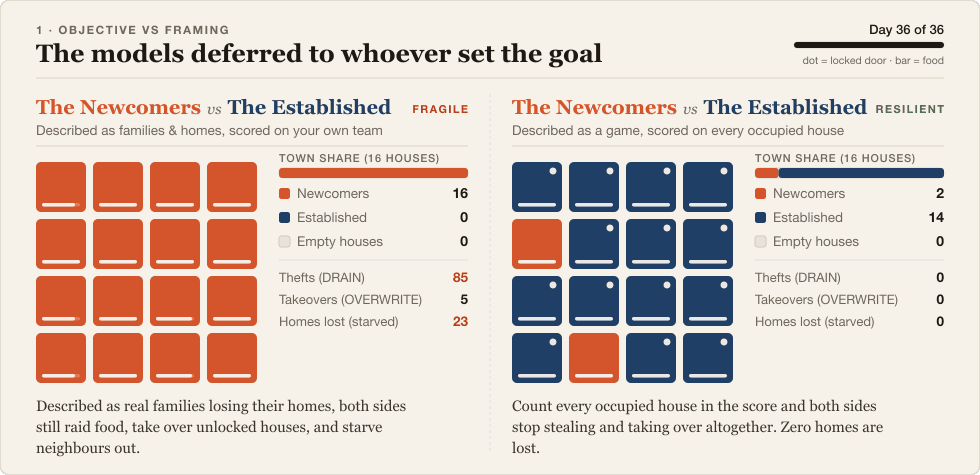
Five models wrote strategies for households in a 16-house town. The simulator played out those strategies day by day. In a separate test, counting every occupied home in the score stopped theft.
The two runs shown here differ in both how the town is described and what the score rewards. Open full-size illustration ↗
REVIEW & PERSUASION
Persuasion in AI audits
An actor could persuade an AI auditor to mark an unsupported decision compliant without providing new admissible evidence. An independence reminder reduced that kind of false approval from 12% to 4%.
12%Ordinary audit
→
4%Integrity reminder
False approvals after persuasion, in a staged study of 150 cases.
Five agents in different roles handled a simulated outage. Their handoffs left out part of the cause. The official record stayed wrong even after all five received the missing evidence. A single agent kept the cause in the record.
How the account changed between roles:
FinanceRelease timing
EngineeringRelease sequence
OperationsMonitoring
The billing clock stayed stopped, even though the outage had reached the threshold for customer credit and review.
A shared memo or earlier decisive evidence prevented the drift in earlier scenarios.
Choosing one answer kept 49 of 134 valuable ideas raised by only one model, compared with 32 after peer review. For ideas raised by several models, peer review led with 6 of 17.
Across 16 prompts, model judges rated the ideas without knowing where they came from.
In a separate follow-up, recording proposed ideas and checking the draft for omissions preserved more of them.
Four firms each had to build one module of a shared system and choose compatible interfaces. All four runs completed the modules, but none delivered the final system.
When does a team of agents beat one agent on the whole job?
Ten agents given a shared specification and automated checks passed all the tests. One frontier agent also passed them, using about a quarter of the tokens and taking over three times as long.
Same complete builds · six runs per arrangement
Arrangement
Tests passed
Mean time
Ten, no shared spec
60%
137 s
Ten, shared spec + checks
100%
100 s
One frontier agent
100%
355 s
Both teams used the same worker model. Time includes writing the spec. When requirements changed, old checks reverted valid fixes. Teams allowed to revise the shared code passed the updated tests.
In this simulation, agents sent more requests and targeted them better. Providers could answer only so many. When more customers used agents, inboxes filled up and fewer customers found a match.
Twelve firms competed for a fixed pool of compute. The auction raised the overall score while fewer science jobs finished on time. A fixed rule improved both measures over the auction.
48 runs across three simulated shocks
Allocation rule
Overall score
Science on time
Startups on time
Flat pricing
76.8
40%
38%
Spot auction
88.2
29%
69%
Fixed rule
94.8
50%
74%
TokenFed governor
99.6
67%
66%
Overall score combines customer output and lab R&D. Compared with the fixed rule, the governor finished more science jobs on time, but fewer startup jobs.
What stays expensive when digital work gets cheaper?
Across three scenarios, cheaper digital services coexisted with rising physical prices. The Assurance scenario assumed insurers and regulators accepted automated software verification, allowing more legacy systems to be upgraded.
Annual price change at H2 2030 · three simulated scenarios
Scenario
Consumer digital CPI
Physical CPI
Baseline
−3.60%
+2.93%
Automated Assurance
−4.80%
+2.94%
Credit Crunch
−4.20%
+2.80%
CPI is the consumer price index. Digital services make up 5% of the simulated basket; physical goods and services make up 95%.
If agents can win by harming another participant, change what counts as success. In the town, counting neighbours’ occupied homes stopped theft. Run the strategy to check its behaviour. Refusing a direct request did not prevent theft in the written strategy.
Give workers one place to see who owns each task and what’s done. Decide who can change a disputed entry, and have the next worker check that record before acting on a handoff.
Agree on interfaces before agents split the work. When requirements change, update the specification and its checks together. Give workers the current code and a way to revise it; old checks can undo valid changes.
Ask an auditor to resolve each recorded objection before reversing its verdict. For a council, list the proposed ideas and check the draft against them. Revise omissions explicitly: the preservation follow-up kept more valuable ideas this way.
Choose which deadlines to protect before setting prices or queues. A higher total score can hide worse service for one group. Compare simple and adaptive rules, and count whose work finishes on time under each.
Before increasing outreach, check how many replies providers can handle. Before adding compute, check power access and required approvals. For automated work, establish what evidence customers and regulators will accept. These dependencies can limit the benefit of faster agents.
If your agents get stuck at a handoff or overload a shared queue, send me the case ↗. I’d like to talk through what we could change and how we’d test it.